Non-Engineer Codebase Access for PMs and Support Teams
Read-only codebase access lets PMs and support teams answer their own questions.
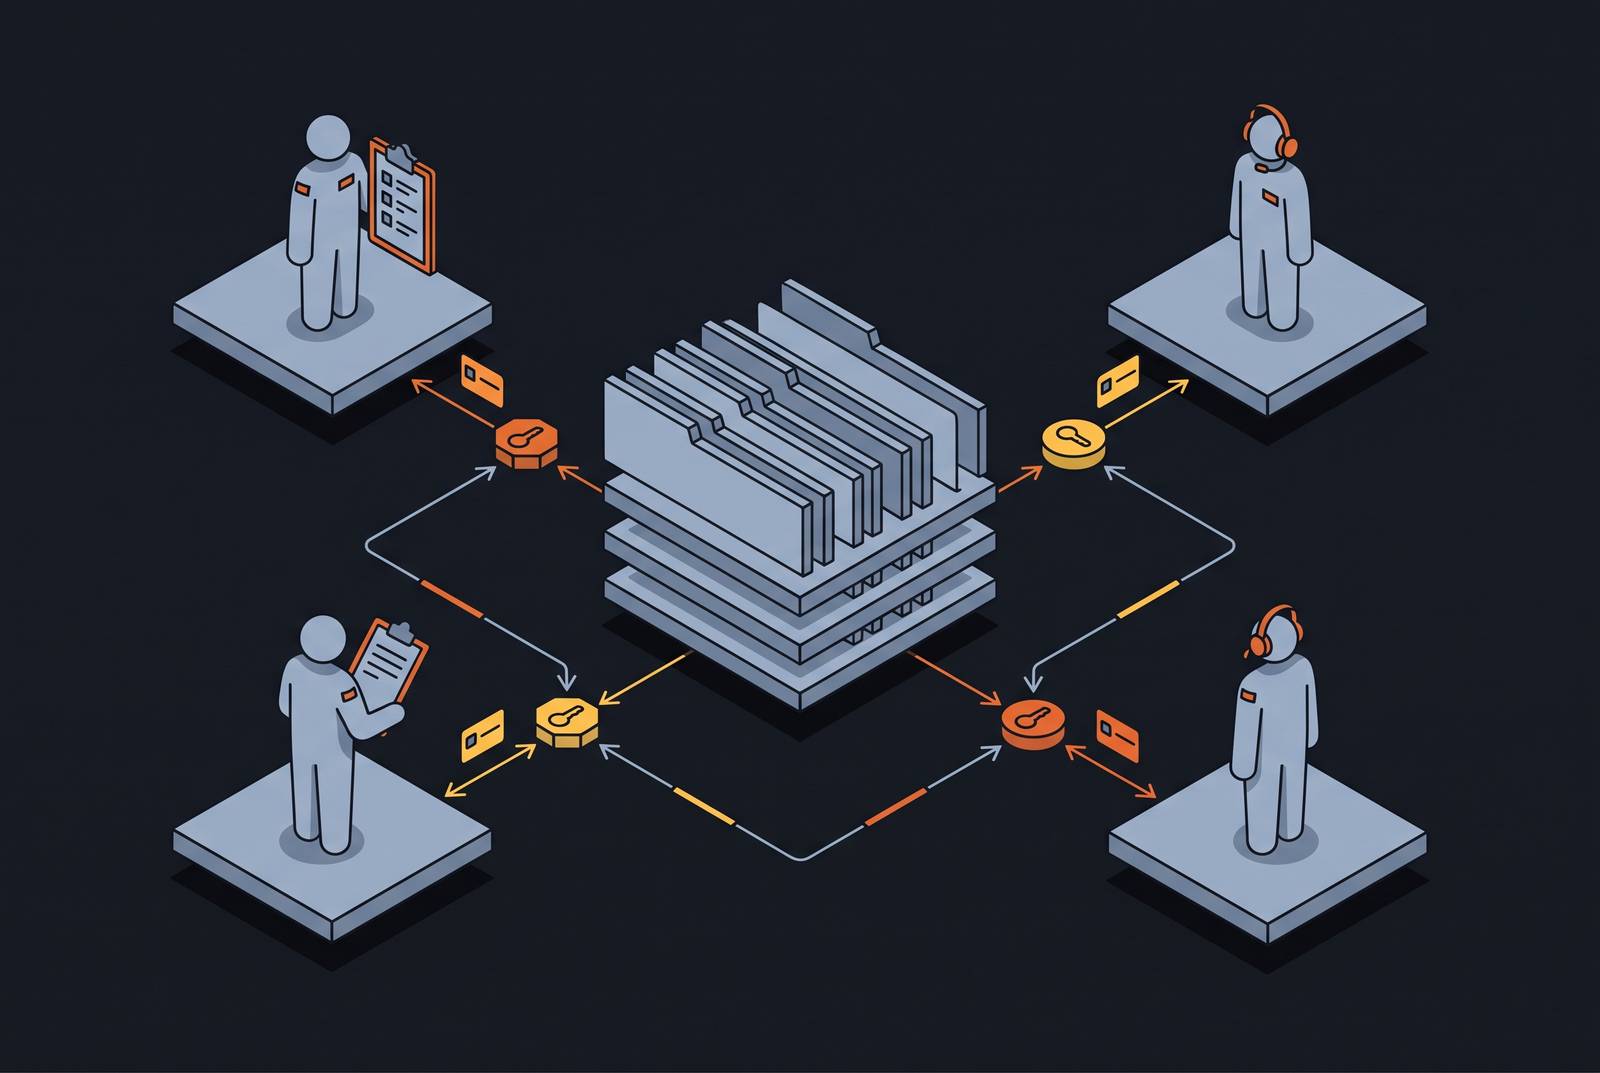
Product managers and support staff have never had a direct line into the codebase, and that absence is a design flaw rather than an unavoidable fact of how software teams work. The standard product development loop, PRD, estimate, build, QA, feedback, took shape largely because non-engineers had no way to touch or read the code themselves. The spec was the only lever available to them, so every team built its process around that limitation. Any question with an answer that lives in the codebase, how the auth flow works, where payment data gets stored, whether a bug is even reproducible, has to route through an engineer, which turns a thirty-second lookup into a scheduled interruption. Support teams hit the identical wall: a customer reports strange behavior at checkout, and without codebase access the only available path is a sync with engineering that burns time on both sides before anyone has confirmed there's even a bug to fix. None of this is a skills problem in any deep sense. It's a tooling problem: reading code has required a local environment, familiarity with repo structure, and knowledge of the stack, and non-engineers have never had a practical reason to acquire any of it. The situation has a close analogue on the other side of the product org. An engineer who could only describe a design change to a designer and then wait has never been an acceptable way to build software, yet that has been the PM's permanent relationship to code.
What non-engineers need from a codebase
Non-engineers need answers from a codebase, not authorship over it, and most access programs fail because they collapse that distinction. A PM's questions are investigative and contextual: how does this feature actually work, what does the schema look like, what did the team build versus what the PRD described, and where does a piece of in-flight work currently stand. Support's questions are diagnostic by nature: is this behavior a bug or intended design, what logic sits behind a given error, has this exact issue come up before. For a large share of PM value, read-only access to a repository covers it completely, letting someone explore and question the code with zero risk of touching anything that runs in production. A second, smaller category of need exists alongside the investigative one: lightweight contribution, things like copy changes, small UI tweaks, or new analytics events. These are real and valuable, but they are not architecture decisions, and treating them as if they required the same judgment as a schema migration is where things go wrong. What PMs do not need matters just as much as what they do: the ability to write production code unsupervised, debug a gnarly technical issue, review code for correctness, or make architectural calls. Conflating codebase access with those responsibilities is the single biggest source of engineering resistance to opening things up.
The interrupt burden on engineers and locked-out non-engineers
The PM who can't get an answer and the engineer who keeps getting asked for one are describing the same broken system from opposite ends, and solving it for one side solves it for both. Every question a PM or support staffer can't answer independently becomes an interrupt in some form, a Slack ping, a meeting request, a sidebar dragged out of standup, and each one forces an engineer to drop whatever they were doing and switch context. That switching cost is not trivial. Regaining deep focus after an interruption takes real time, and an engineer fielding a steady stream of informational requests can lose a significant share of a working week to questions that involve no actual engineering. The volume of this is only going up: as AI coding agents help teams ship code faster, codebases grow faster too, and they become harder for non-engineers to reason about without tooling built for the purpose, which raises rather than lowers the interrupt load on the engineers who wrote the code in the first place. This is why the productivity case for non-engineer codebase access lands best as an engineering-team benefit. Engineering leaders are the ones who end up unlocking it, and they do it for their own reasons. At epilot, adding Claude to production alerts meant incidents got investigated, logs got read, and fixes got proposed before most engineers had even opened the dashboard. The interrupt simply never happened.
What meaningful codebase access looks like for PMs
Once a PM has working access to the codebase, the shape of their contribution to product development changes: they start arriving at conversations with evidence. When a user reports a confusing checkout issue, a PM with access can trace through the relevant code, understand the logic behind it, and walk into the meeting with specific questions about the decision points they found, so triage happens before the escalation. The same access lets a PM check what the team actually built against what the PRD said, without needing an engineer to reconstruct a decision that was made six months earlier. It also changes feature planning: a PM can use the codebase to see how a proposed feature would interact with existing functionality before the PRD gets written, not after the fact when the conflicts are harder to resolve. For small changes, copy, layout, a UI tweak, a pull request communicates more precisely than a Slack thread ever could. The PM gets exactly the change they wanted, and the engineer reviews a specific diff. At epilot, non-engineers described what they wanted in plain product language, one request read "when creating a new family in the Label Builder, the drawer should close automatically," and the agent located the right repositories and implementation details without the PM needing any knowledge of the underlying stack. The same access reshapes prototyping: a PM can go from identifying a problem to having a working prototype inside one session, replacing a static wireframe with something stakeholders can actually click through, so the demo exists before anyone has to request a slot in the sprint.
What codebase access unlocks for support teams specifically
Support teams get a distinct kind of value from codebase access, one centered on diagnosing customer issues without turning every question into an engineering request. Support's question is almost always the same shape: is this behavior a bug or working as designed, what's the logic behind a particular edge case, has this exact error surfaced before. Without access, every ambiguous customer report forces a choice between a guess ("I'll check with engineering") and a full interrupt. With access, support can triage before escalating, handing engineering a characterized issue. At epilot, support staff used Claude to ask product questions directly rather than hunting down the engineer who happened to know the answer, and it became the fastest way to understand how anything worked across five years of accumulated code history. That knowledge asymmetry is sharpest in companies with long-lived codebases, years of decisions, deprecated paths, and undocumented edge cases that no single engineer fully remembers, and a natural-language interface into that history serves support better than any internal wiki ever could. Intercom gave Claude Code to more than 1,000 non-engineers, including marketers, sales leaders, PMs, and customer success teams, and over 300 of them became active weekly users. That adoption happened organically rather than through a mandate, which says something about how real the underlying need was.
Why "they'll break things" misidentifies the actual risk
The engineering objection to non-engineer codebase access is usually some version of "they'll break things," and the concern is reasonable, but it points at the wrong target. An agent operating inside a non-engineer's session with access to production systems, real credentials, or any path to live customer data is the genuine risk. That risk has nothing to do with whether the person driving the session is a PM or an engineer. It's an infrastructure exposure, and it gets solved at the infrastructure layer regardless of who's asking the questions. A second, smaller risk involves PR quality: non-engineer contributions can come in large, inconsistent with team conventions, or architecturally confused. At one company, a designer working without guidance produced a 10,000-line pull request that mixed copy tweaks and CSS changes with a full new feature, backend work included, that Claude had solved by mocking everything underneath it. The lesson from that case is about scope and pairing, not about shutting the door on access. The strongest version of the objection, that non-engineer PRs just add review load without actually freeing up engineer time, deserves to be taken seriously. It holds true for large, complex contributions. It does not hold for the small, scoped changes that represent the actual appropriate use case: copy, UI, analytics events. Pairing each non-engineer contributor with a specific, named engineer reviewer turns review into a process question rather than a blanket veto, so a PR never just floats in a Slack channel hoping someone eventually picks it up.
What the underlying infrastructure needs for safe, low-overhead access
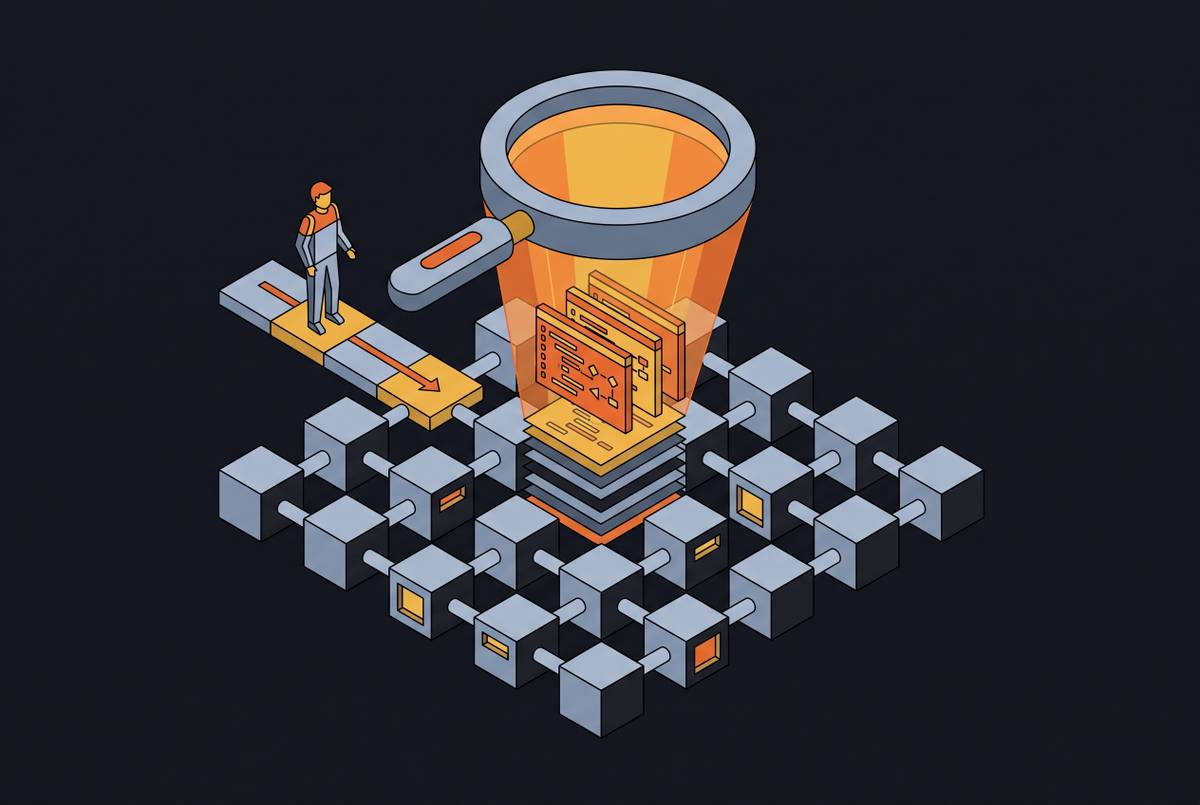
Whether non-engineer codebase access works smoothly or creates chaos comes down almost entirely to infrastructure, and most of what it requires is probably already on an engineering team's roadmap for other reasons. Sandboxed developer environments need to start with a single command, since non-engineers can't be expected to manage local environment setup the way an engineer would. At epilot, one GitHub repo bootstrapped a developer sandbox with a shallow copy of all 219 company repositories, cloned and ready with tools configured within minutes. Automatic preview environments per PR matter even more for this audience than for engineers: every PR needs to generate a live preview link in CI, because a non-engineer who can't see and interact with their own change has no real way to confirm it did what they intended. Agents also need indexed institutional context to produce output that fits a codebase's actual conventions; without it, output reads as generic. Epilot built an internal knowledge base called "how-to-everything," covering API patterns, backend conventions, code style, CI/CD strategy, business context, domain terminology, and the full RFC archive, and that context is what separated usable output from noise. Scope constraints need to be enforced at the environment level: production systems mocked, no live credentials anywhere in a non-engineer's environment, no path to real data, built in from the start. Before any of that contribution work happens, though, non-engineers need a way to find relevant code in the first place, one that doesn't assume familiarity with repo structure, file naming conventions, or the underlying stack. Sourcebot addresses that layer directly: it deploys as a single Docker container inside a company's own infrastructure, indexes every repository, and gives both human users and AI agents a natural-language interface to the codebase, so the code itself never leaves the environment, a detail that matters considerably once support staff or PMs are asking questions that touch customer data or proprietary logic. Natural-language search tools in this category remove the prerequisite of knowing the repo layout or the tech stack, which is what makes read-only exploration practical for people who have never opened a terminal. MCP-based connectors to tools like Jira, Linear, or Confluence round this out, letting an agent answering a PM's question about a feature cross-reference the issue tracker and the codebase in a single session, without forcing the PM to bounce between tools to piece the answer together themselves.
How to scope the rollout to build engineering confidence
Teams that have made non-engineer codebase access work did not roll it out by announcing an open-door policy to the whole company. They built a narrow, well-supported path first and let adoption spread from there once people saw it working. Starting with read-only investigative access rather than contribution lets PMs query the codebase and support staff diagnose issues, delivering value immediately, carrying close to zero engineering risk, and giving non-engineers a chance to build familiarity with the codebase before they attempt to change anything in it. Epilot ran three one-hour onboarding sessions, one for design, one for support, one for go-to-market, and that single decision drove more adoption than anything else the company tried. PMs didn't even need a session of their own; they picked it up from watching the pattern work elsewhere. Pairing each non-engineer contributor with a named engineer reviewer before their first PR goes up ensures a rotation or a "whoever's free" arrangement doesn't leave the on-call engineer inheriting the review by default. Contribution scope should be stated explicitly from the start, covering UI changes, copy, and analytics events, while excluding backend logic, schema changes, or anything touching a production data path, with the understanding that the constraint is a starting point. The first wave of contributions functions as a calibration exercise: what got reviewed quickly, what sat open too long, what needed significant rework, and those answers should shape the scope and pairing model for the second wave. At epilot, within 60 days every team had at least one person who had contributed to the codebase using Claude Code, and adoption spread organically from there without engineering having to push it. The payoff runs deeper than the productivity numbers suggest. Non-engineers who have actually read and touched the codebase write sharper PRDs, file more precise bug reports, and ask better questions in technical reviews, because codebase access doesn't just let them do new things. It changes the quality of every artifact they were already producing.