Making Monorepos Navigable for Engineers on Day One
Semantic code search transforms monorepos from overwhelming to navigable on day one.
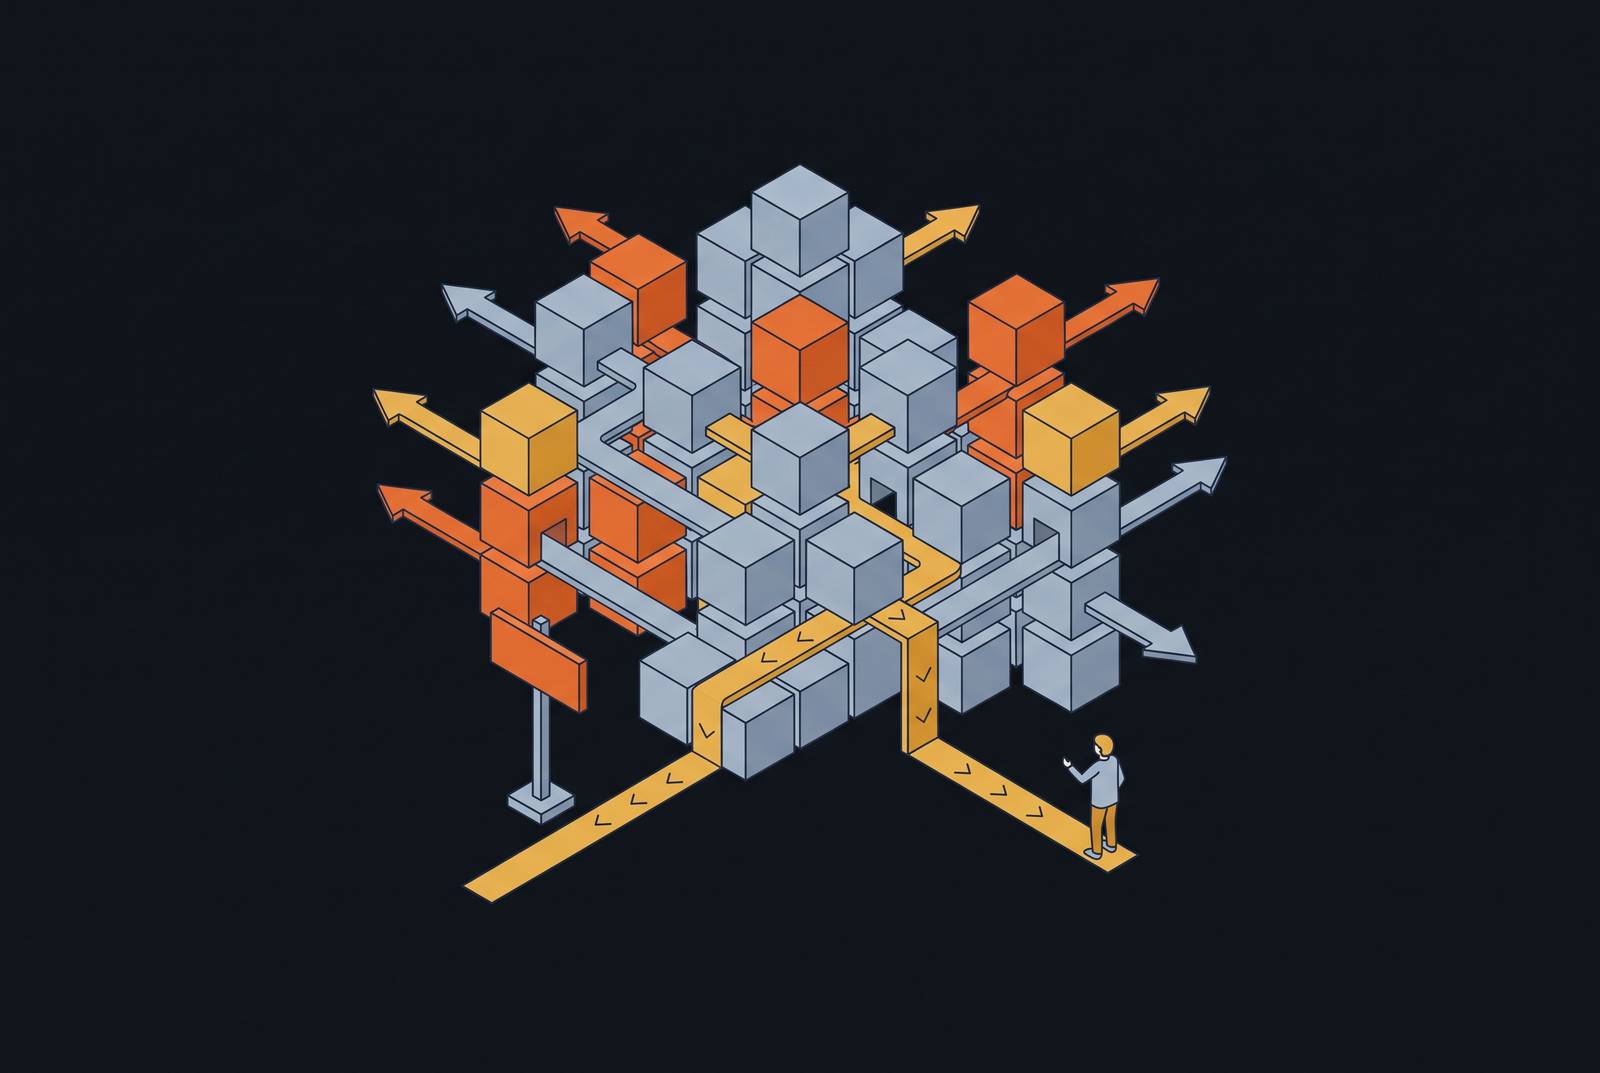
A monorepo promises to end the fragmentation that engineers have endured for decades: one clone, one environment, one place where all code lives. The promise is conditional. It only delivers if an engineer can actually find the code that matters to them, and at enterprise scale, most monorepos fail that test. The difference between a monorepo that onboards engineers and one that overwhelms them is not architectural. It is whether the codebase is navigable on day one.
Why monorepos create an onboarding paradox at enterprise scale
The structural case for a monorepo is genuine. A single clone removes the synchronization tax that polyrepo sprawl imposes, unified tooling eliminates the per-repository setup that consumes a new hire's first week, and one source of truth means cross-team code is visible from the moment an engineer checks out the tree. These advantages are not marketing claims. They are real properties of the architecture. For a company consolidating dozens of repositories into one, the immediate wins in CI simplicity and dependency management are measurable.
The inversion happens silently. A codebase that spans many services, libraries, and teams gives a new engineer no signal about where their work lives, what depends on what, or where to start reading. The very property that makes the monorepo valuable, everything in one place, becomes the property that makes it impenetrable. The consolidation benefit inverts into a navigation penalty.
This is not an argument for returning to polyrepos. The evidence documents what happens when monorepos lack navigation tooling, not a structural flaw in the monorepo model itself. A polyrepo with equally poor search and discovery suffers the same problem, just distributed across more surfaces and with more friction to even begin looking. The architectural choice is not the variable that determines onboarding speed. The variable is whether a new engineer has a fast, indexed, queryable surface for the codebase from the moment they sit down. Companies that recognize this distinction fix the right problem. Companies that conflate the two either abandon a sound architecture or invest in tooling that solves a different issue entirely.
What actually blocks a new engineer in a large monorepo on day one
The blocking mechanisms are navigational, not conceptual. New engineers know how to write code. The directory tree is not a map. It's a list of names that only makes sense to people who already understand the system.
Without navigable tooling, the path to understanding runs through other engineers. A question gets asked in a Slack channel. A thread grows. A pairing session gets scheduled. Each step interrupts someone who was doing something else, and each interruption carries a hidden cost that compounds. The knowledge-transfer loop becomes the primary bottleneck in onboarding, not because anyone is failing to communicate but because the architecture of the codebase offers no alternative. This interrupt-driven knowledge extraction is the mechanism that turns a monorepo's theoretical visibility into practical opacity.
Two distinct populations face this problem. New engineers need to locate service boundaries, understand dependency graphs, find the file that owns a behavior, and trace a call chain without a guide. The build-orchestration tier, Turborepo, Nx, Bazel, solves a different problem: it answers what needs to rebuild now that this PR touched these files. The day-one questions remain unanswered, and the people who know the answers remain interrupted.
Why build orchestration tools don't close the navigation gap
Build orchestration and code intelligence are complementary layers that solve different problems. Conflating them is the reason most monorepo tooling conversations miss the navigation gap entirely. When a team adopts a monorepo and discovers that engineers are lost, the default response is to reach for a build tool, because build tools are the category of software most visibly associated with monorepos. It's a dependency graph optimized for determining what needs to recompile, not for answering what a human being needs to know.
The tools in this category are genuinely good at what they do. None of them answer the questions a new engineer asks on day one: where is the service that handles X, what calls this function across the repo, show me every place we use this API, what changed in this area last month. These are navigation questions, and build tools have no surface for them. Adding a build orchestration layer to a monorepo that lacks navigation tooling is like adding a faster engine to a car with no windshield: the speed improves, but the driver still can't see where they're going.
Meta's Glean illustrates what a purpose-built code-intelligence layer looks like. It includes a query language that can ask structural questions like what are the direct subclasses of X, a capability no build tool has a surface for. Glean is the clearest evidence that the problem of code navigation at scale is a distinct engineering discipline, not a feature that build orchestration will eventually grow into. The existence of this category, and its adoption at companies that operate the largest monorepos in the world, confirms that the navigation gap requires its own solution. Sourcebot occupies this same layer for enterprises that need semantic search across private codebases without the operational investment that a system like Glean demands.
What fast cross-repo code search actually makes possible for a new engineer
Fast, indexed, semantic code search converts the monorepo from a maze into an explorable graph. A new engineer can locate relevant code, trace dependencies, and understand ownership without extracting that knowledge from another person. The transformation is not incremental. It changes the fundamental mechanism by which onboarding happens. The knowledge-extraction loop that runs through Slack channels and pairing sessions collapses into a query. The senior engineer's context is preserved, the new engineer's momentum is maintained, and the codebase itself becomes the teacher.
The specific capabilities that change day-one behavior are fourfold. Cross-repository symbol search lets an engineer find every definition of a function or type across all packages without knowing which package owns it, which matters because ownership is precisely what a new engineer lacks. Reference and call-chain navigation traces what calls a function and what it calls, spanning service boundaries that are invisible from the file tree alone. Commit and diff search reveals what changed recently in an area of the codebase and why, a critical signal for a new engineer trying to understand intent rather than just current state. Natural-language querying lets a non-engineer or a very new hire ask where the payment retry logic lives and get a direct answer from the index rather than from a colleague. Each of these capabilities removes a question from the interrupt pipeline.
The interrupt elimination argument is measurable in aggregate. Every question a new engineer answers via search is a question that does not interrupt a senior engineer. That calculation alone justifies the investment. The monorepo's theoretical visibility becomes actual visibility, not just for engineers but for everyone whose work touches the code.
How to evaluate a code intelligence layer for a monorepo environment
Not all code search tools are built for monorepo scale or enterprise privacy requirements. The evaluation criteria that matter in a large, private codebase are different from those that matter for open-source navigation. A tool that works well searching GitHub's public repositories may collapse when pointed at a tree with millions of lines and strict compliance constraints. The criteria that determine fitness for a large enterprise monorepo are specific and testable.
Indexing architecture is the first filter. Can the tool handle a repo of millions of lines with incremental updates, or does it re-index from scratch on every change? At enterprise scale, a full re-index can take hours, which means the index is stale by the time it completes. Deployment model follows. Does code leave the company's infrastructure during indexing or querying? For enterprises under regulatory pressure, this is often a hard constraint, not a preference, and it eliminates any hosted-only option immediately. Total cost at scale rounds out the evaluation: what does the per-engineer cost look like at 200 engineers, or at 500? Many tools price attractively for small teams and become prohibitive at the scale where the navigation problem is most acute.
The options documented in this space fall into distinct profiles. It powers IDE features, code search, and automated analysis such as unused-code detection. A second consideration applies across all options: teams should retain control over which LLM provider processes their code and where queries are sent. The bring-your-own-model capability belongs on the evaluation checklist alongside the index architecture.
How a code intelligence layer fits into the AI agent workflow inside a monorepo
An AI coding agent starting a task in a large monorepo faces exactly the same orientation problem as a new engineer. It knows nothing about the repo and must find its way by searching for strings and opening files, spending most of its context budget on files that don't matter and still missing the one that does. The context window that determines what an agent can reason about fills with irrelevant code before the agent ever reaches the function it needs to modify. The result is the same failure mode the human engineer experiences: wasted effort, wrong guesses, and the need to ask for help that may not be available. The problem is structural, and it does not care whether the actor lacking orientation is a person or a model.
The emerging solution is a context layer, a pre-built index the agent queries over MCP instead of re-reading the file tree. Such tools ingest repositories, parse them to their AST representations, extract entities and relationships, and commit the result to a queryable graph that any MCP-compatible agent can access. The agent asks the index for the files that matter to its task, receives a precise answer, and spends its context budget on relevant code rather than discovery. Loading every available tool into every agent session is a costly anti-pattern that dilutes context and slows response. Scoped configuration avoids it.
The privacy implication is sharper for agents than for human search. A context layer that resolves queries locally and returns only the relevant files to the agent, which then sends a minimal prompt to the inference provider, changes the privacy calculus fundamentally. Teams evaluating a code intelligence layer for agent use should ask not only where the index lives but where the queries and the retrieved code go next.
How to help new engineers get productive faster in a large codebase
The difference between a monorepo that overwhelms and one that onboards is whether the new engineer has a fast, indexed, queryable surface for the codebase from the moment they sit down. Without it, the first day follows a predictable path: clone the repo, open the directory tree, read the README, ask a senior engineer where the payment service is, and get a thirty-minute pairing session as a substitute for documentation that never existed. With it, the first day looks different: the new engineer queries the index for the payment service, gets file locations, traces call chains, reads relevant commit history, and identifies owners, all without opening a Slack message. The difference is not in the engineer's ability or the team's willingness to help. It's in whether the codebase answers questions directly or funnels every question through the most expensive available resource: another engineer's time.
The onboarding artifact that code search makes viable is auto-generated, per-module READMEs and repo maps that stay accurate because they're derived from the live index rather than written once and left to drift. A new engineer reading a module's generated map sees the current call graph, not the one that existed six months ago when someone last updated the markdown. This is documentation as a property of the system rather than a promise kept by people who have other priorities.
The interrupt elimination is measurable in aggregate. Every new engineer who can self-serve their orientation questions returns hours to the senior engineers who would otherwise have answered them. Across a cohort of new hires, this compounds into meaningful capacity recovery. Ten new engineers each saving a handful of questions per day returns what amounts to a substantial portion of a senior engineer's week. The non-engineer dividend extends the benefit: a product manager who can query every place a payment event is logged without filing a ticket ships faster and interrupts the team less. This is a benefit the monorepo's theoretical visibility always promised but only a code intelligence layer actually delivers. The decision is no longer whether to make the codebase navigable but when, and the answer can be today.